If you’ve spent any time preparing for coding interviews, you’ve run into Two Sum. It’s one of the most commonly asked questions out there — and also one of the most commonly memorized rather than actually understood.
Here’s the problem: given an array of numbers and a target value, find two numbers in the array that add up to the target.
nums = [2, 7, 11, 15]
target = 9
# Expected output: indices of 2 and 7, since 2 + 7 = 9
Simple to state. Worth actually understanding properly — because the way you get from the naive solution to the optimal one is a pattern that shows up constantly in real-world backend work, not just interviews.
The instinct everyone starts with
The first approach almost everyone reaches for is brute force: check every possible pair of numbers until you find one that adds up to the target.
nums = [2, 7, 11, 15]
target = 9

for i in range(len(nums)):
    for j in range(i + 1, len(nums)):
        if nums[i] + nums[j] == target:
            print(f"Found: {nums[i]} + {nums[j]} = {target}")
This works. Run it, and you’ll correctly get 2 + 7 = 9. So what’s wrong with it?
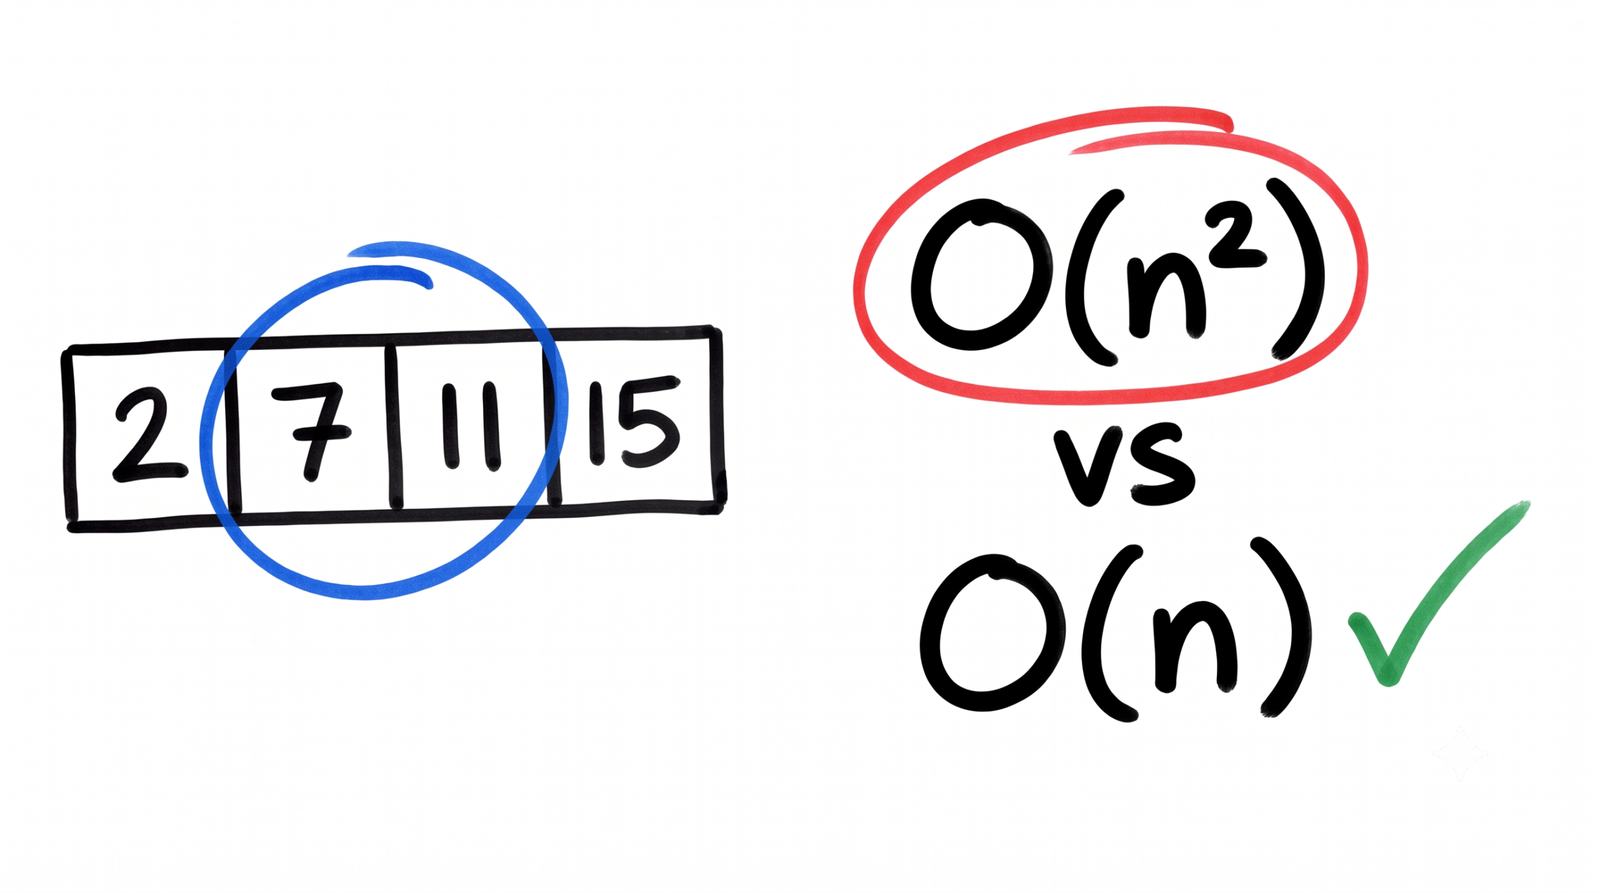
The problem shows up at scale. For every number in the array, this approach checks almost every other number. With 4 elements, that’s a handful of comparisons — trivial. But with 1,000 elements, it’s roughly 500,000 comparisons. With 1,000,000 elements, it balloons to around 500 billion. This is what’s known as O(n²) time complexity — the amount of work grows roughly with the square of the input size. It doesn’t just get slower as your data grows; it gets slower much faster than your data grows.
The reframe that fixes it
Here’s the actual insight that makes this problem click: you don’t need to check pairs at all.
Instead, ask one question for each number as you go through the array: “Have I already seen the number that would complete this pair?”
If the target is 9 and you’re currently looking at 7, the real question isn’t “what’s 7 plus every other number” — it’s simply “have I already seen a 2?” If yes, you’re done. If no, remember that you’ve now seen a 7, and move to the next number.
This turns a nested, repetitive search into a single pass with one lookup per step.
Building it, with the logic exposed
Here’s the same idea in code — with print statements added so you can see exactly what the algorithm is “thinking” at each step:
nums = [2, 7, 11, 15]
target = 9
seen = {}

for i, num in enumerate(nums):
    needed = target - num
    print(f"Step {i}: looking at {num}, need {needed}, seen so far: {seen}")
    if needed in seen:
        print(f"  -> Found! {needed} + {num} = {target}")
        break
    seen[num] = i
Running this produces a trace like:
Step 0: looking at 2, need 7, seen so far: {}
Step 1: looking at 7, need 2, seen so far: {2: 0}
  -> Found! 2 + 7 = 9
Notice what’s happening: seen is acting as memory. At every step, the algorithm checks whether it already has what it needs before doing anything else. That memory is a hash map (a Python dictionary), and hash map lookups are close to instant — regardless of how large the map gets. That’s the entire trick behind the speedup.
The clean version
Once the logic makes sense, the final version you’d actually ship looks like this:
python
def two_sum(nums, target):
    seen = {}
    for i, num in enumerate(nums):
        needed = target - num
        if needed in seen:
            return [seen[needed], i]
        seen[num] = i
One loop instead of two. O(n) instead of O(n²).
Why this matters beyond the interview
The speedup here didn’t come from writing cleverer code — it came from asking a different question. That’s the actual transferable skill: noticing when you’re repeating work that you could simply remember instead.
| Approach | Time Complexity | What it does |
|---|---|---|
| Brute force (nested loop) | O(n²) | Checks every possible pair |
| Hash map lookup | O(n) | One pass, one lookup per step |
This exact pattern — trading a small amount of memory for a large amount of speed — shows up constantly in real backend work: caching repeated lookups, deduplicating records, avoiding N+1 database queries. Two Sum is a small, contained way to practice noticing it.
What’s next
This is the first video in Think in Patterns, Not Problems — a series that focuses on the pattern behind each problem, not just the answer to memorize. The next one builds on this same instinct with a different problem. If you want to follow the full series in order, the playlist is linked below.
Watch the full walkthrough (with the live trace) here: https://youtu.be/UXNBl2boAYw
Full playlist: https://www.youtube.com/playlist?list=PLTyiXpqKeCvQ